Introduction
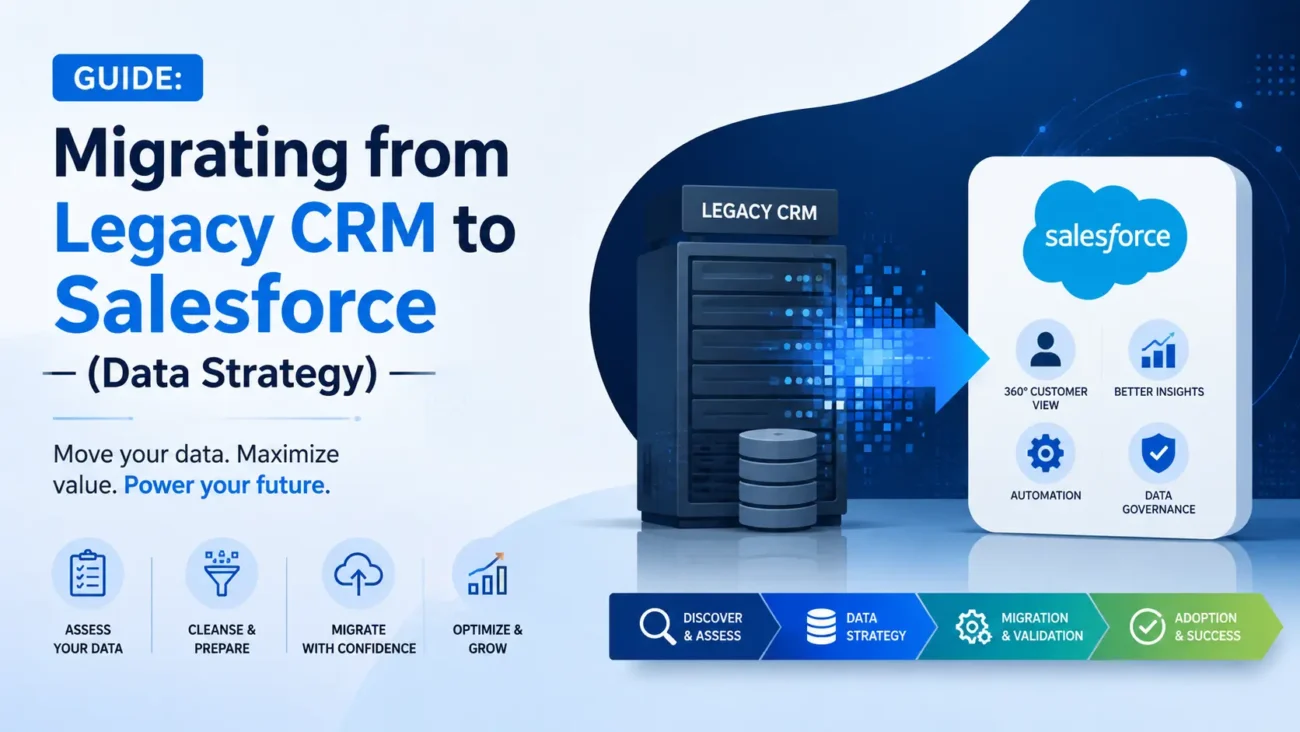
A legacy CRM migration is often planned as a lift-and-shift: export everything, import everything, switch the system off. The safer approach treats a Salesforce CRM migration as a controlled redesign of business information. You keep the history that still has operational or reporting value, clean the records that need correction, preserve the identifiers required for traceability, and leave obsolete data behind. A planned Salesforce data migration also gives the team room to resolve mapping and ownership problems before they reach production.
A platform move gives the team a reason to correct old data-model decisions before they become permanent parts of the new Salesforce environment. This is the same principle that applies to a Salesforce Revenue Cloud implementation, where carrying old structures into a new platform can preserve problems that the migration should have removed.
TL;DR
A legacy CRM to Salesforce migration works best when the data strategy is agreed before files are prepared. Start by listing every source that contributes customer, sales, service, activity, or reference data. Decide which source owns each field and which records qualify for migration. Keep the untouched source extract so every transformation can be traced back to its origin.
Design the Salesforce object model before field mapping begins. If the migration is part of a wider CRM rebuild, the target architecture should be settled as part of the Salesforce implementation before detailed mapping starts.
Clean duplicates and controlled values before the production load. Salesforce uses matching rules and duplicate rules to identify and handle potential duplicate records, so those controls should be included in migration testing.
1. Define the migration scope before you design the load
Start with a source inventory. A company that calls the project a CRM migration may still have customer data spread across several places. The legacy CRM might hold accounts and opportunities, while an ERP owns billing accounts, a support platform holds cases, and spreadsheets contain territory assignments or renewal dates.
Those dependencies matter because unclear source ownership is also a common cause of Salesforce integration problems. Decide which system owns each important field before the migration or integration starts moving records between platforms.
Finance systems deserve particular attention. A business using accounting software may have customer, invoice, payment, or order information outside its CRM. The same ownership questions appear in a Salesforce QuickBooks integration, where sales and finance data need clear boundaries before synchronization makes sense.
Source-specific issues also belong in scope. Microsoft Dynamics 365 may use option sets and ownership patterns that need value mapping. HubSpot may represent lifecycle state differently from Salesforce Lead and Contact handling. Zoho CRM can contain custom stages or fields without a direct Salesforce equivalent. Teams moving between those platforms can review the broader Zoho vs Salesforce CRM differences before deciding how old concepts should appear in the target model.
Service information may come from a separate support platform or an older CRM module. Open Cases and useful customer history should be mapped around the operating model planned for Salesforce Service Cloud so agents retain the context they need after cutover.
2. Design the Salesforce data model before field mapping
Field mapping should follow the target design. Starting with legacy columns encourages the team to reproduce a structure built around old technical limits or retired processes.
Accounts, Contacts, Leads, Opportunities, Cases, Campaigns, Products, and other standard Salesforce objects already have defined behavior across the platform. Object choice should follow business meaning, which the name of the source table often obscures.
A legacy table called “Customers” may map to Accounts, Person Accounts, or a mix depending on what its records represent. A legacy “Deals” table may map to Opportunities if the records describe potential revenue. A contract register can require a different design.
Account and Contact identity rules affect almost every downstream relationship. Decide how the organization will identify the same company when names vary, subsidiaries exist, or several billing entities sit under one brand.
For Accounts, useful identifying attributes can include ERP customer IDs, registration numbers, approved domains, source-system keys, or another reviewed identifier.
Finish these target-model decisions before treating the field-mapping workbook as final. A migration can reveal wider configuration problems too. Where the existing Salesforce environment already contains duplicate objects, unused fields, or conflicting automation, a focused Salesforce CRM cleanup can help separate migration defects from problems already present in the target org.
3. Profile and clean the source data before production loading
Data cleanup belongs before the production import. Bad records become harder to untangle once Salesforce relationships, automation, duplicate rules, integrations, and user edits start acting on them.
Profiling should measure the fields that affect identity and business use. Check null rates, duplicates, invalid values, unexpected lengths, date ranges, owner validity, orphan relationships, and controlled-value drift.
| Review area | What to measure | Migration risk | Practical response |
|---|---|---|---|
| Account identity | Duplicate names, domains, tax IDs, ERP IDs | Duplicate Accounts split revenue and activity | Define match and merge rules before loading |
| Contact identity | Duplicate emails, shared emails, missing Account links | Contacts can become duplicated or orphaned | Set a match hierarchy |
| Opportunity data | Stage, amount, close date, owner, Account | Pipeline totals can change | Reconcile active pipeline |
| Controlled values | Values outside target lists | Failed loads or bad reporting groups | Build an approved crosswalk |
| Ownership | Inactive or unknown users | Records can reach the wrong owner | Map users or queues |
| Relationships | Missing or invalid parent references | Child records can become orphaned | Repair or route exceptions |
Deduplication needs business rules. Exact matching on one field can miss duplicates, while loose fuzzy matching can combine records that represent different customers.
Preserve the raw source extract unchanged. Every corrected or transformed dataset should be reproducible from that source.
4. Build the Salesforce data mapping as an executable contract
A Salesforce data mapping workbook should tell another qualified person how to recreate the migration.
For each target field, document the source field, source meaning, target meaning, transformation rule, null behavior, relationship method, validation check, and decision owner.
Keep original identifiers where they help traceability. A source key can support reruns and make it easier to connect related records.
Salesforce documents the use of an External ID for importing related records. An External ID can let Data Loader associate a child record with its parent using a source-system identifier in place of the Salesforce record ID in every source file.
Field names still need semantic review. A legacy “Created Date” may describe when a row entered the old CRM, while another system holds the actual date the customer relationship began.
The mapping workbook should also record fields that won’t migrate. That makes exclusions deliberate and heads off late requests to create custom fields for unused columns in an old export.
5. Preserve record relationships with External IDs and load order
Relationships make load order important. Salesforce creates new IDs for newly inserted records, so dependent records need a reliable way to identify the right parent.
A practical load sequence may be:
- Load users, queues, or required reference records.
- Load Accounts or the primary customer entity.
- Load Contacts and other Account-dependent records.
- Load Opportunities once Account and ownership references can be resolved.
- Load dependent products, Cases, junction objects, or custom records.
- Load activities, notes, files, and history after their referenced records exist.
Many-to-many relationships can require junction records after both sides are loaded. Account hierarchies can need an additional update pass after all parent and child Accounts have IDs.
Salesforce also documents limits around External IDs for polymorphic fields such as activity WhatId and WhoId, so those relationships need testing before anyone assumes they behave like standard lookups.
Before each major load, review Salesforce’s data import best practices, including CSV structure, supported formatting, test imports, error files, and large-load timing.
6. Choose the migration tool by volume and control needs
Tool choice should follow the workload.
Salesforce’s Data Import Wizard supports up to 50,000 records at a time for supported objects. It can fit smaller browser-based imports where the object coverage and operation types meet the project’s needs.
For larger jobs, Salesforce documents Data Loader as a bulk import and export option, including insert, update, delete, and export operations for larger record sets.
| Tool | Good fit | Main consideration |
|---|---|---|
| Data Import Wizard | Smaller supported imports | Lower setup effort but narrower scope |
| Data Loader | Larger or repeatable data work | Better control over mappings and result files |
| API or staged process | Complex dependencies or repeated migration runs | Requires engineering, logging, and recovery controls |
Projects with several systems can require middleware or a staging architecture in addition to the import tool. Salesforce MuleSoft integration services are relevant when data continues moving between Salesforce, ERP, finance, service, or other platforms after the migration has finished.
A staging layer can store raw extracts, corrected records, transformed outputs, value crosswalks, exception records, and load status. That gives the migration team a repeatable path from the source snapshot to the Salesforce import files.
7. Test migration quality with business evidence
Testing should prove that Salesforce can support real work with migrated records.
Import result files show whether Salesforce accepted a row. Business validation determines whether the row has the correct owner, relationship, status, value, visibility, and reporting meaning.
Validation should cover technical errors, source-to-target counts, important totals, relationship integrity, business processes, permissions, and integrations.
Permission testing deserves its own check because data can migrate correctly and still be unusable if users can’t access it. Salesforce’s permissions and access settings determine what users can access and which actions they can perform.
Use representative business records during testing. Include the difficult cases alongside the clean examples.
Run at least one full-volume rehearsal in a suitable nonproduction environment with the same mappings, transformation logic, load order, automation settings, and validation approach planned for cutover.
User acceptance should also test how people work. Sales users should be able to find customers, review contacts, inspect pipeline, update opportunities, and use expected reports. Support users should be able to find customer history and work current Cases.
Clean data still fails operationally when people can’t use the new process. Planning Salesforce adoption and user enablement alongside testing helps identify where users need role-specific guidance before go-live.
8. Plan cutover, delta loads, rollback, and legacy access together
Cutover is the controlled switch in system authority. The runbook should state when source changes stop, when the final extract begins, how changed records will be handled, and who approves each checkpoint.
The rollout method also affects migration risk. HyphenX’s comparison of Salesforce implementation approaches explains the trade-offs between a single cutover, phased migration, and temporary parallel operation.
Before making destructive changes or running the final migration, keep a source and target backup. Salesforce’s guidance on how to back up Salesforce data recommends keeping backup data before bulk changes that may require manual reversal.
A practical cutover sequence is:
- Confirm readiness and the source-freeze decision.
- Capture the final source extract.
- Run the approved cleanup and transformation jobs.
- Load records in the rehearsed dependency order.
- Reconcile counts, important totals, owners, relationships, and errors.
- Run business smoke tests.
- Approve Salesforce as the active CRM after acceptance checks pass.
- Keep the legacy system under the approved archive or read-only policy.
Delta loads matter when the source CRM can’t remain frozen for the full migration window. Define how changes will be identified and how updates or deletes will be reconciled.
Rollback should also be written in business terms. The runbook needs a clear decision point, an authority for making the call, and a method for preserving work completed during the migration window.
9. Treat post-go-live data control as part of the migration
The migration is complete once the Salesforce data can be maintained reliably after launch.
Assign owners for important data domains. Sales operations may own Opportunity stages and pipeline definitions. Customer operations may own Account standards. IT may own system identifiers and integration rules.
Keep controls for duplicates, unresolved ownership, integration failures, data exceptions, and temporary migration fields.
Long-term data controls can also be measured against Salesforce’s data integrity architecture guidance, which covers areas such as source identifiers, data handling, and integrity controls.
The decisions made during migration should remain documented after the project closes. HyphenX’s guidance on Salesforce implementation documentation and handover covers the operating records needed so the permanent team can understand data ownership, integrations, testing evidence, release procedures, and known issues after the implementation team leaves.
The first few weeks after launch should include comparison against pre-migration business measures. Pipeline by stage, active customer totals, case backlog, ownership distribution, and other important numbers should remain explainable.
Some differences may be intentional because duplicates were merged or obsolete history was excluded. Those differences should still be traceable to an approved migration rule.
Frequently asked questions
1. What should be migrated from a legacy CRM to Salesforce?
Migrate records that support current operations, reporting, audit needs, or known downstream processes. Active Accounts, Contacts, open Opportunities, open Cases, and current reference records often qualify. Older history can remain in an archive when users don’t need it in Salesforce.
2. How long does a legacy CRM to Salesforce migration take?
The timeline depends on source count, data quality, target design, relationship depth, integrations, testing requirements, and the cutover window. Estimate the timeline after source profiling and confirm it through rehearsal.
3. How much data can the Salesforce Data Import Wizard load?
Salesforce currently documents a limit of up to 50,000 records at a time for the Data Import Wizard on supported objects.
4. When should a team use Salesforce Data Loader?
Data Loader fits larger or repeatable bulk operations where the project needs greater control over inserts, updates, upserts, exports, deletes, mappings, and result files.
5. Why are External IDs useful during migration?
External IDs preserve source-system identifiers. They can help with upserts, traceability, reruns, and supported parent-child relationship loading.
6. Should duplicates be cleaned before or after migration?
Material duplicates should generally be resolved before the production load when the business has a safe matching and merge rule. Uncertain matches can remain in an exception process for review.
7. How should historical CRM data be handled?
Keep history in Salesforce when users need it for current work, reporting, customer context, audit requirements, or another defined purpose. Older records can remain in an archive when Salesforce doesn’t need them operationally.
8. How do you validate a Salesforce migration?
Compare source and target counts, business totals, relationships, owners, permissions, import errors, integration behavior, and user scenarios. Acceptance should depend on those results, with import completion as only one of them.
9. What causes CRM migration problems?
Common causes include unclear scope, poor source profiling, unresolved duplicates, incomplete relationship logic, missing source identifiers, untested automation, integration gaps, and weak cutover controls.
10. What should a Salesforce migration checklist include?
The checklist should cover source scope, mappings, transformation rules, ownership, relationship order, migration tools, automation behavior, duplicate controls, backups, delta logic, validation, user testing, rollback criteria, and legacy access.
